This chapter has been written in order to ensure that all GUTS data can be considered as one massive dataset, by having all sites convert their data in the same way. The following data types will be covered:
Questionnaires
(f)MRI
EEG
Behavioral data
Physiological data (e.g., ecg, skin conductance, dynamometer output)
Processed data should not contain sensitive participant data (IP addresses, first- and last names, date-of-birth, postal codes, etc.)
Sensitive tabular information should be saved in a different (secured!) location.
(f)MRI scans should be defaced
Participant id columns have to be named “participant_id” according to BIDS standards
Questionnaire data
You can find some example data cleaning scripts (R) here.
There is also an R script available that can (automatically) retrieve and save Qualtrics survey results in R, as well as upload the retrieved data to Yoda. Please find it here.
Step 1: Exporting questionnaires from Qualtrics.
Export the raw data from qualtrics as a .sav file and rename the file to
The extension .sav is used to ensure that Qualtrics gives the right output, as .csv or .tsv sometimes gives faulty output. The cleaned file will not be a .sav file.
Make a copy of this file and store it in a secure folder. This way you have one file that stays as raw data and another you can clean using this handbook as
Step 2: Setting up scripts and opening file.
Open the .sav file in Rstudio, SPSS, or any other preferred program. Before making any adjustments to your file, make sure to open a script file in which you can save every step taken while processing (e.g., R script/R Markdown file + R Project) in R, SPSS Syntax). Your scripts could be saved in the same folder as your data or in a subfolder called scripts (e.g., gutseur_ses-01_quests-part-02_script-raw-to-processed.r)
Step 3: Set up a data cleaning log file.
While processing data, make sure you log any anomalies and any decisions made. For example, log any found duplicates, which of these were removed, and why. You could document this in the R/SPSS script but you could also opt to create a separate log file. Also document who cleaned the data and at what date.
Step 4: Check for duplicates, empty rows, and correct participant ids.
Before you remove any unnecessary variables and sensitive information, check for duplicates and empty rows. In case of duplicates, it is advised to keep the entry with most progress. For two entries with exactly the same progress, the last entry should remain. It is also important to check whether the participant id is correct.
Additionally, remove all entries without data, this includes entries that only provided demographic data but did not respond to any questionnaire.
Step 5: Remove sensitive information(!) and unnecessary variables.
Processed data on Yoda should not contain any identifiable information, such as IP address, first- and last names, e-mail addresses, postal codes, date-of-birth, etc. This information should be saved in a different location on a secured drive. In the processed file for each questionnaire should only be participant id and questionnaire items.
Step 6/7: Check for correct variable names, variable labels, values, and value labels.
Ensure that all variable names adhere to the GUTS naming conventions. Additionally, make sure that variable labels correspond to naming conventions and, in case of overlap, are equal for each cohort. The same holds for values and value labels - All variable names, values, value labels need to correspond to the item-level metadata that can be found on the GUTS Sharepoint. Additionally, ensure that the values and labels correspond to official values, whether the correct values and value labels were exported from Qualtrics correctly, and that they are equal for each cohort.
Step 6/7: Create separate files for each questionnaire.
Each questionnaire should get their own file, according to the following naming convention:
guts[location]_ses-[session]_task-[short-name]
Step 8: Create metadata files and convert .sav file to .tsv file.
Processed files on Yoda should be in tsv format. You can choose to also keep a sav file to be able to automatically create JSON files (see Chapter 15).
In addition to processed files, there is the option to create a derivative file for each questionnaire. In case of questionnaire, a derivative file would consist of only participant id and sum/total scores of a questionnaire. For example, for the questionnaire “Strengths and Difficulties Questionnaire (SDQ)”, with five subscales, the derivative file would contain the following variables:
*desc stands for description and describes what kind of data is derived from the primary file.
(f)MRI data
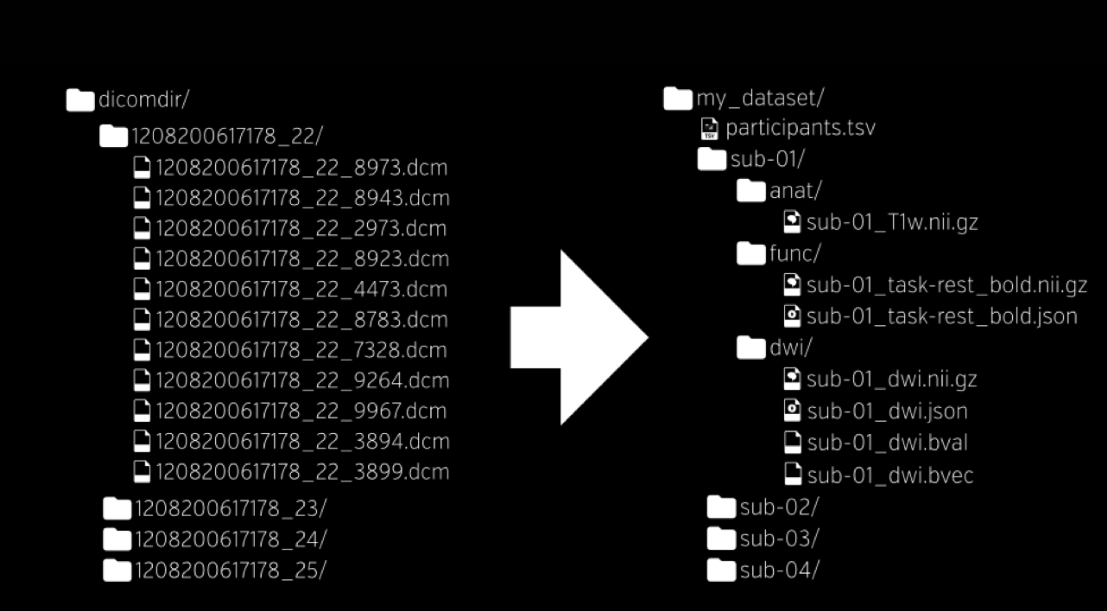
Raw output from (f)MRI data might differ between locations, e.g., only DICOM files or .nii, .par and .rec files. Bidsifying (organizing and naming of files according to the BIDS standard), however, should happen in a similar way for all outputs. There are several programs one can use to bidsify data to limit manual labor. See the BIDS website for more information about options. Please refer to Chapter 12. Specific naming conventions and Chapter 13. Data structure while BIDSyfing. After BIDSifying, a pipeline (fMRI Prep/HALFpipe) can be used for further (pre-)processing. A pipeline is currently being developed and will be shared once finished.
Example of a prebidsified and a bidsified data structure
EEG data
Raw output from EEG data might differ between locations depending on programs/materials used. However, BIDSified data should end up looking the same. There are several ways in which EEG data can be automatically BIDSified. (see the BIDS website). After BIDSifying, a pipeline can be used for further (pre-)processing. This pipeline is currently being developed and will be shared once finished.
Behavioral tasks
Behavioral tasks can yield data from tasks during EEG, ECG, (f)MRI, Dynamometer, but also from tasks conducted solely on a computer/e-prime without being linked to any sort of biological/physiological information. For all behavioral tasks, a group-level file has to be created so that group analyses can be performed based on all participants’ scores, for example. Additionally, individual files of behavioral tasks will be processed and relocated according to BIDS to facilitate individual analyses.
Physiological data
Physiological data could include ECG data, skin conductance data, and grip force data (dynamometer). The raw output will differ depending on the programs/materials used. Nonetheless, all output should be BIDSified (named and located according to BIDS standards) before further (pre-)processing.
ESM data
ESM data will be processed similarly to the Qualtrics questionnaire data.
Biological and Genetic data
Hair and saliva samples will be send to a lab for analysis. After analysis, you will receive files that should be processed to adhere to the guts standard.